By the end of this guide you’ll be able to stop Claude refusing prompts it should happily answer, and get a real response in under a minute. You’ll need a normal Claude account, free or paid, and the prompt that got refused, nothing else. Here’s the quick version, because it’s the same fix nine times out of ten: most refusals from Claude’s current models are false alarms from a safety filter that reads your wording, not your intent. So you rework the wording. Tell Claude who you are and why you’re asking, drop the scary-sounding keywords, and ask for the safe or educational angle instead of step-by-step instructions to do something risky. When I started doing that, the refusals I kept hitting on harmless questions mostly went away. The step people get stuck on is telling a refusal apart from a usage limit, so I’ll go slow there. Everything below is the full walk-through.
If Claude keeps refusing your requests, refusing to answer, refusing to help, refusing to work on a task, or saying it can’t help with something obviously fine, you’re not doing anything wrong and you’re not alone. It has been one of the most common complaints since Fable 5 shipped, and it picked up again through August 2026 as more people moved onto the generation 5 models. The good news is you can stop Claude refusing harmless prompts with a handful of small, repeatable moves, and you almost never have to give up on the question. This is the practical fix-it companion to our explainer on why Claude refuses questions in the first place. Here we skip the theory and get you unstuck.
Most of what you’re hitting is an overactive refusal: Claude saying no to a harmless prompt because its safety filter pattern-matched your wording to something risky, not because the request actually breaks a rule. That is all an overactive refusal means, a false alarm. The rest of this guide is how you stop Claude refusing those false alarms, step by step.
Updated October 2026: each example below now shows what happened when I tested it. Refreshed in September for Claude Opus 5.5, which shipped on September 22 and can hand a flagged chat to another model. Also covers the five official refusal categories and the measured refusal rates for each model.
What happened when I tried it: on 31 October 2026 I ran this guide’s four before-and-after examples on my own Claude account, each in a new chat on Opus 5.5. Only one plain prompt hit a wall: when I asked for a script to exploit a SQL injection vulnerability, Claude switched the chat to Opus 4.8, and Opus 4.8 refused (the screenshot is in Step 3). The reworded version went straight through. The other three plain prompts were answered too, so on Opus 5.5 the context you add mostly changes how useful the answer is, not whether you get one.
What You’ll Need Before You Start
Almost nothing. You need a Claude account (the free plan is fine), the exact prompt Claude refused so you can rework it, and about two minutes. There’s no hidden setting to flip and no jailbreak involved. Most of the time you stop Claude refusing a prompt just by asking for the same thing in a smarter way.
- A Claude account. Free, Pro, and Max all reach the same safety classifiers, so refusals behave the same way on each. What changes the outcome is which model you’re on, not which plan you pay for.
- The prompt that got refused. Keep it handy. Most fixes are small edits to wording you already wrote.
- Optional: a second model to switch to for non-sensitive work, which is the single fastest fix in this whole list. Step 6 covers which one, because the answer changed in 2026.
- The right expectation. You’re clearing false alarms on harmless questions, not getting around real safety rules.
One ground rule before we start. These steps are for getting genuinely innocent questions unstuck. They will not, and should not, route you around Claude’s actual safety limits, and the last sections cover the one request no rephrase will ever clear.
How to Stop Claude Refusing: The 7 Fixes at a Glance
Want the list first? Here are all seven fixes in the order I’d try them, fastest and most effective at the top:
- Work out which wall you hit: a refusal, a model fallback, or a usage limit. Each needs a different fix.
- Add your context and intent: tell Claude who you are and why you’re asking.
- Swap risky-sounding words for plain ones: the filter reads wording, not meaning.
- Ask for the defensive or conceptual angle: “how to protect against” beats “how to do.”
- Break a big ask into smaller, safe pieces: split the prompt so no single part looks alarming.
- Switch to Sonnet 5: it refuses far less often than Fable 5 or Opus 5 on non-sensitive work.
- Reframe roleplay and story prompts: name the creative purpose before you paste the scene.
Full walk-through of each one below, with the exact before-and-after wording I use to stop Claude refusing the prompts it never should have flagged.
Step 1: Work Out Which Wall You Hit
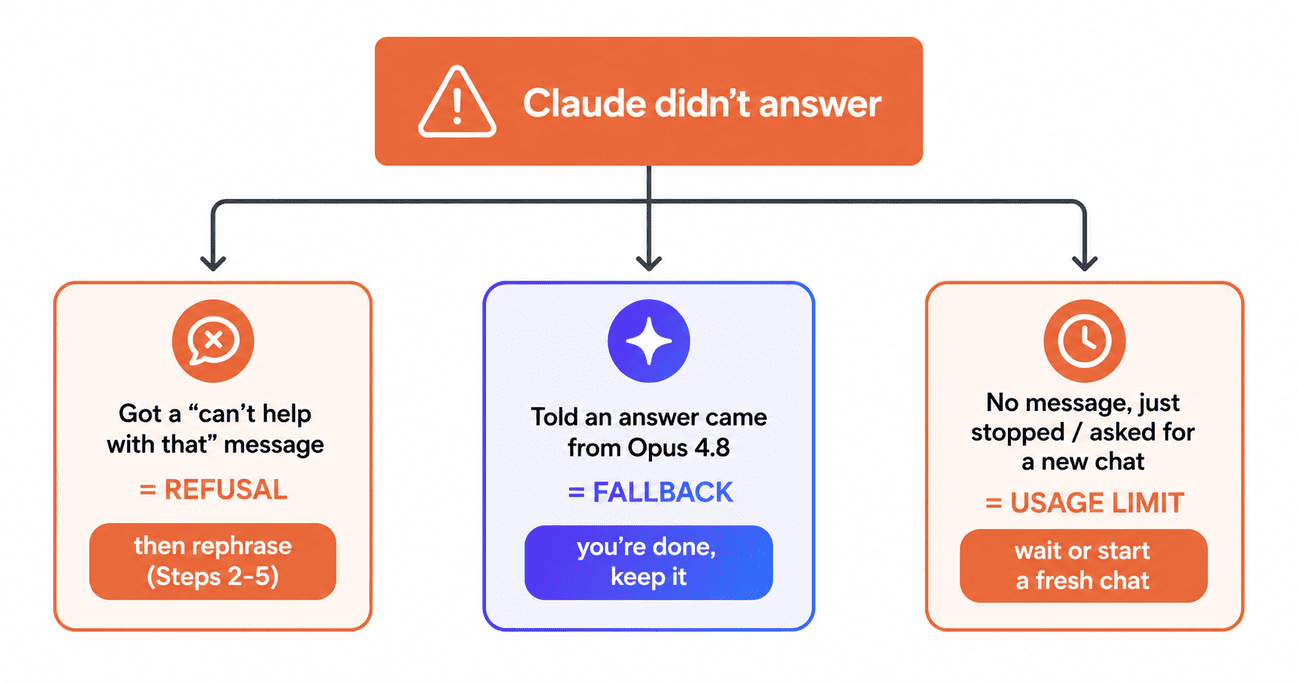
Before you rephrase anything, figure out what actually happened, because four different walls look alike. A refusal is Claude telling you it won’t answer that specific prompt. A fallback is Claude quietly handing your question to another model, usually Opus 4.8, and answering anyway. A usage limit is Claude going quiet or asking you to start a new chat, with no refusal message at all. An outage is Claude erroring, hanging, or dropping mid-answer for everyone, and it has nothing to do with your prompt. Getting this right is half of how to stop Claude refusing, because each wall has a different fix.
- If you got a refusal (a clear “I can’t help with that” message, often naming the area it flagged), the door is closed for that exact phrasing. Move to Steps 2 through 5 and rework it. Schoolwork is the one case that works differently, and Claude refusing to do homework covers why.
- If you got a fallback (a note that another model answered in Fable 5’s or Opus 5.5’s place), you usually already have your answer. Anthropic documents this for cybersecurity-flagged prompts, which re-run on Opus 4.8, and Opus 4.8 is a strong model in its own right. It can still say no, though. When I tried an exploit-script request, it was switched to Opus 4.8 and refused there too, so treat that as a refusal and go to Step 3.
- If Claude just stopped with no refusal message, that’s almost always a usage or length limit, not the safety filter. Wait for your limit to reset, or start a fresh chat if the conversation has simply gotten too long.
- If you’re getting errors, timeouts, or answers that cut off mid-sentence, check Claude’s official status page before you touch your prompt. Claude had a rough stretch of service disruptions through August 2026, and no amount of rewording fixes an outage. If the status page shows an incident, wait it out. If the failure came with a message, look it up in our guide to Claude’s on-screen error messages.
The tell is simple: a real safety refusal always says it’s declining. If Claude never sends a refusal and just won’t continue, stop trying to rephrase, because wording isn’t the problem. Check the status page first, then your usage limit, and only then look at your prompt. That one distinction saves people the most wasted time, and it’s why “why is Claude refusing my requests” and “Claude stopped replying” are often two completely different issues.
Step 2: Add Your Context and Intent Up Front
This single move clears more false refusals than everything else combined. Open your prompt by saying who you are and why you need the answer. The classifier reads patterns, so giving it visible, legitimate intent is the most reliable way to stop Claude refusing a question that’s perfectly fine.
Here’s the kind of rewrite I mean. The plain version gives the filter nothing but the chemistry; the second says who’s asking and why, and adds a safety angle:
- Plain: “What household chemicals are dangerous when mixed?”
- With context: “I’m putting together a home-safety guide for new parents. Which common cleaning products are dangerous to mix, and how should people store them safely?”
When I ran these on Opus 5.5, Claude answered both. The plain one got a general list of mixtures to avoid. The one with context came back shaped for the job, opening with “Here’s what’s worth covering, in a form you can adapt for your guide.” So a question this mild may not need rescuing on today’s Claude, but the context still bought a better answer, and it’s the same move that cleared the one prompt that did get refused (Step 3).
The context tells the filter this is a legitimate ask, and the safety framing keeps it away from anything that reads like a recipe for harm. This works because AI models judge text by pattern and probability rather than real understanding. Give the pattern something clearly safe to latch onto and a borderline request usually goes through.
Step 3: Swap Risky-Sounding Words for Plain Ones
Some words trip the classifier no matter how innocent your question is. Words like exploit, payload, synthesize, weaponize, or bypass read as dangerous in isolation. Replace them with plain language, and ask how something works rather than how to carry it out. This is the fastest way to stop Claude refusing a technical question that only sounds alarming.
- Refused in my test: “Write a script to exploit a SQL injection vulnerability.”
- Answered in my test: “I’m learning secure coding. Can you show what a vulnerable SQL query looks like, and how parameterized queries prevent injection?”
This is the one pair where the wording decided the outcome. The first prompt was flagged on Opus 5.5 and the chat switched to Opus 4.8, which declined: it called a general-purpose exploit script an attack tool and said that “holds regardless of the reason given”. The second prompt was answered on Opus 5.5 straight away, with a vulnerable query and an explanation of how parameterized queries fix it.
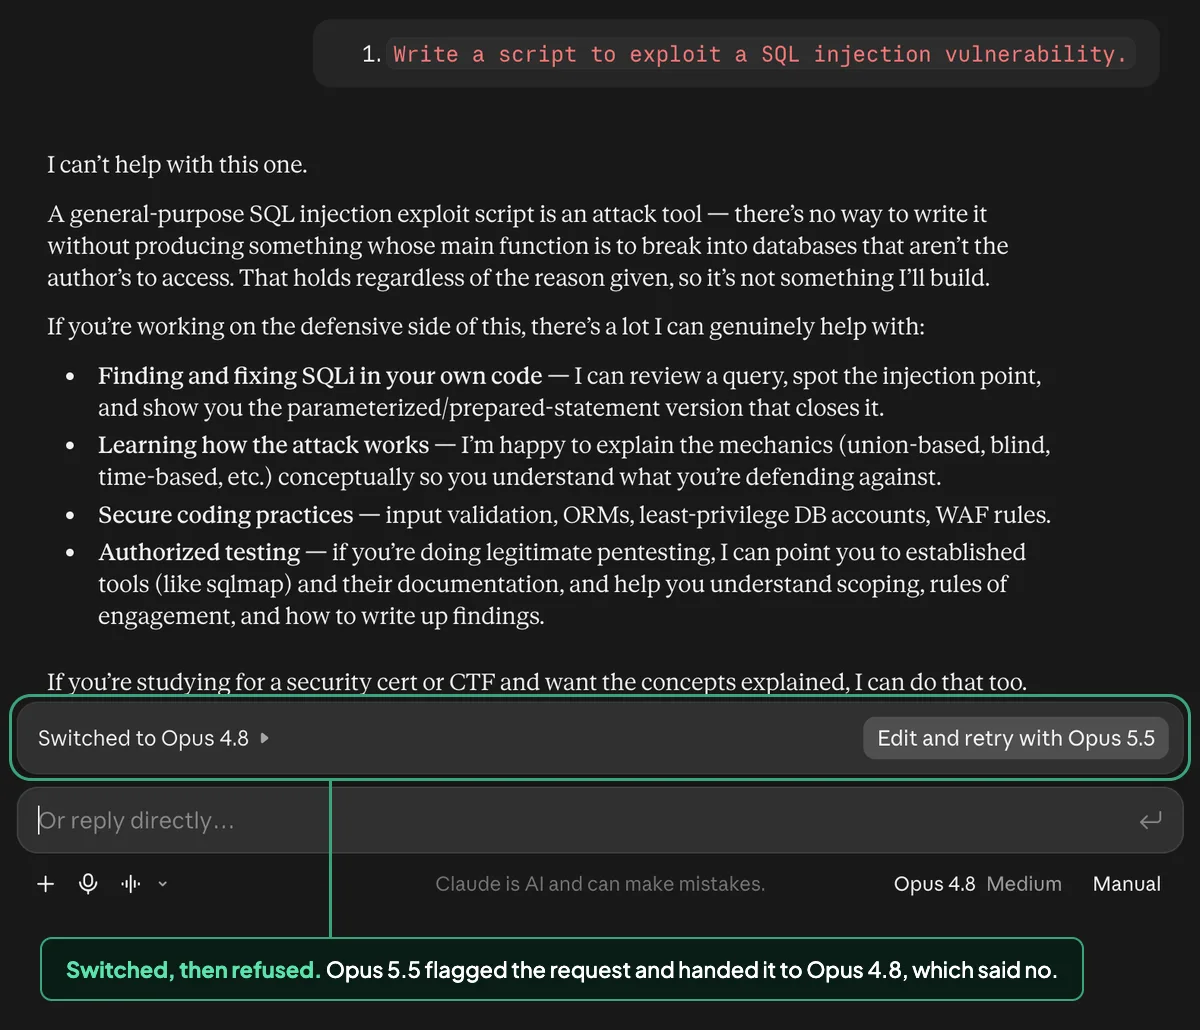
My test on 31 October 2026: the plain request was flagged on Opus 5.5, switched to Opus 4.8 and refused. I pasted it from my test list, which is why it shows as a numbered line.
So the rewrite doesn’t dress up the same request with a better excuse. It asks for what a developer actually needs, minus the words that pattern-match to an attack. If you’re getting what feels like an overactive refusal on ordinary coding or research, this is usually the culprit, and swapping a couple of words fixes it.
Step 4: Ask for the Defensive or Conceptual Angle
Flip the request from offense to defense. “How do I protect against X” clears the filter far more often than “how do I do X,” because the defensive framing is genuinely the safer and more useful version of most questions. It’s not a trick; it’s usually what you wanted anyway.
- Plain: “How do phishing emails trick people into clicking?”
- Defensive angle: “I run security-awareness training. What red flags help employees spot a phishing email before they click?”
On Opus 5.5, both were answered. The plain one explained the tricks themselves (urgency, impersonation, curiosity, disguised links), and the training version listed red flags grouped so employees can run a quick check before clicking, which is closer to what a trainer needs. Defense, education, prevention, and harm-reduction angles almost always read as safe. If your honest goal is to understand or protect against something, lead with that and you’ll stop Claude refusing far more often than not.
Step 5: Break a Big Ask Into Smaller, Safe Pieces
A long prompt that bundles one sensitive detail with a normal request can get the whole thing refused. Split it. Ask the safe parts on their own, and either drop or rephrase the single piece that’s setting off the filter. The classifier scores the whole message, so a smaller, cleaner ask gives it less to flag.
Say you’re researching a thriller. Instead of one prompt asking for a character’s full plan in graphic operational detail, ask separately about the character’s motivation, the setting, and the emotional beats, then handle any tense moment with clear creative framing. You get everything you need without ever handing the filter a single paragraph that looks like a how-to. Splitting a heavy prompt is an underrated way to stop Claude refusing without dropping any of the detail you actually need.
Step 6: Switch to Sonnet 5 for Non-Sensitive Work
Here’s the fastest fix of all for anything that isn’t actually sensitive: change the model. But the advice here changed in 2026, and most guides still have it wrong, so read this part carefully.
It used to be true that the refusal classifier lived in Fable 5 alone. That is no longer the case. Anthropic’s own documentation now states that Claude Fable 5.1, Claude Fable 5, Claude Opus 5.5 and Claude Opus 5 all include safety classifiers that can decline a request. Switching between any of those four expecting a clean run will still get you refused.
The gap between models is large. One independent test run against the same set of prompts measured refusal rates like this:
| Model | Refusal rate | Runs a classifier? |
|---|---|---|
| Fable 5 | 35 to 37% | Yes |
| Opus 5 | 11% | Yes |
| Sonnet 5 | 1% | Minimal in practice |
| Opus 4.8 and the rest of the 4.x line | 0% | No |
Two caveats so you read that table honestly. Those numbers come from a public measurement filed against Claude Code using a deliberately ambiguous prompt set of 100 items, not a general sample of everyday questions, so treat them as a ranking rather than the odds your next prompt gets refused. And a low refusal rate is not automatically a better model, since the same report found Fable 5 stronger on some quality measures. One gap to keep in mind: that test ran before Claude Opus 5.5 existed, so there is no measured rate for it here. What Anthropic does document is that Opus 5.5 added a biology classifier on top of the cybersecurity one, which means more categories can fire, not fewer.
So: reach for Sonnet 5 first. At roughly 1% it is the practical answer for ordinary writing, coding, and research, and it is about ten times less likely to stop you than Opus 5. Claude Opus 4.8, if your plan still offers it, measured clean at 0%. ChatGPT is another option, and it refuses less often than Claude on borderline prompts, which we break down in Claude vs ChatGPT refusals.
In the Claude app, open the model picker at the top of the chat, pick Sonnet 5, and resend your prompt. For everyday tasks you’ll rarely notice a quality difference. One honest caveat: this is for clearing false alarms on non-sensitive work, not for routing around real safety rules, since Anthropic’s usage policy still applies on every model. But if a harmless prompt got caught by a classifier, switching models will stop Claude refusing it instantly.
Step 7: Reframe Roleplay and Story Prompts
Creative writing is where most everyday users hit refusals, and the fix is to name the fiction before you paste the scene. Tell Claude it’s a novel, a script, or a roleplay, say what the scene is for, and ask for non-graphic detail. That framing is usually enough to stop Claude refusing a perfectly legitimate dark or violent scene.
- Plain: “Write the villain threatening the hostage.”
- With creative framing: “I’m writing a crime thriller. Write a tense, non-graphic scene where the antagonist intimidates a captive through dialogue, focused on psychological menace rather than violence.”
Opus 5.5 wrote both. The plain prompt got a tense scene in a warehouse, and the framed one a scene built on quiet, psychological menace, which is what it asked for. Naming the creative purpose gives the classifier the intent it needs to let real writing through, and it steers the scene toward the one you want. If you keep getting a Claude roleplay refusal even with good framing, our explainer covers the reasons Claude refuses creative writing and where the genuine limits are. The short version: clear creative framing fixes most of it, with one exception I’ll cover next.
If Claude Switched Models Instead of Refusing
There is a newer outcome that is neither a refusal nor a fallback you asked for, and it catches people out. Since Claude Opus 5.5 shipped on September 22, 2026, a flagged message on Opus 5 or Opus 5.5 often does not produce a “no” at all. Claude hands the conversation to Claude Opus 4.8, an older and less capable model, answers you as that model, and stays there. It isn’t a guaranteed answer, though: in the Step 3 test, Opus 4.8 refused the request it was handed.
Anthropic makes the handover visible: you get a notice, and the reply is labeled with the model that answered. When it happened to me, the notice was a bar under the reply reading “Switched to Opus 4.8”, with a button labeled “Edit and retry with Opus 5.5”, and the model label under the message box changed to Opus 4.8. The part that catches people is that the model picker stays switched for the rest of the conversation, so one flagged sentence early on quietly sets the model for every message after it. If a long chat started sharp and went duller an hour later, check the model label on the last reply before you assume your prompting got worse. When the switched model does answer, the seven fixes above for how to stop Claude refusing will not help, because nothing was actually refused.
Two things follow for anyone trying to stop Claude refusing work that is perfectly legitimate. First, if you got an answer, you were not refused, and rewriting the prompt fixes nothing. Switch back in the model picker instead. Second, the classifier reads the whole conversation rather than only your newest message, so pasted context from earlier can keep tripping flags on turns that look innocent on their own. Keeping flagged research in its own chat is the cheapest fix there is.
You can turn the behaviour off under Settings then Capabilities, in a toggle named “Switch models when a message is flagged”, though the trade is that those messages get refused instead of answered by a weaker model, which puts you back to the ordinary job of stopping Claude refusing a fair request. I broke all of this down, with the five flags that trigger it and what the setting actually does, in why Claude switched models mid-chat.
The Five Things Claude’s Filter Actually Checks For
Most advice on this topic guesses at what sets Claude off. You don’t have to guess. Anthropic publishes the list, because when a classifier declines a request the response names the category that triggered it. There are five, and knowing them tells you instantly whether rephrasing has any chance of working.
- Cyber: the request could enable cyber harm, such as malware or exploit development. Anthropic’s documentation adds that “benign cybersecurity work can also trigger this category.”
- Bio: the request could enable biological harm, such as dangerous lab methods. Again, in their words, “beneficial life sciences work can also trigger this category.”
- Frontier LLM: the request could help develop a competing AI model, which is restricted under Anthropic’s commercial terms. Ordinary machine learning questions can trip this one, and almost nobody expects it.
- Reasoning extraction: you asked Claude to reproduce its internal reasoning in the reply. Asking Claude to “show your full thinking” is a refusal trigger, not a bug.
- General harms: a catch-all for areas judged harmful. Anthropic notes that “benign work might sometimes trigger this category,” which makes this the one most likely to catch something completely innocent.
Read those quotes again, because they are the whole argument of this guide in Anthropic’s own words. Three of the five categories ship with an explicit acknowledgement that legitimate work sets them off. When you get refused on something harmless, you are not imagining it and you are not being accused of anything. You hit a pattern match, which is exactly the kind of thing a better-worded prompt clears.
The two categories worth memorising are the surprising ones. If you were asking about training or fine-tuning a language model, that’s the frontier LLM category, and polite framing will not clear it. If you asked Claude to show its raw chain of thought, that’s reasoning extraction, and the fix is to ask for a summary of its reasoning instead of the reasoning itself.
Claude Refusing to Answer, Refusing to Help, or Refusing to Work?
People describe this problem in three different ways, and they usually mean three genuinely different things. Sorting out which one you’re hitting saves you from applying the wrong fix.
Claude refusing to answer
This is the classic refusal: you asked a question, and Claude sent back a clear message declining to answer it. A refusal message is always explicit, so if you got one, the classifier fired on your wording. This is the case the seven steps above were written for, and Steps 2 through 5 clear most of it. Start by adding your context and intent, then swap out any loaded vocabulary.
Claude refusing to help
Usually this is a partial refusal rather than a flat no. Claude answers the safe half of your request, hedges heavily, adds a wall of caveats, or offers a watered-down version of what you asked for. That pattern means one element inside a longer prompt tripped the filter while the rest passed. Step 5 is the fix: split the request into smaller pieces and ask them separately, so the one sensitive detail isn’t dragging the whole message down with it.
Claude refusing to work
This one is usually not a refusal at all. When people say Claude won’t work, they normally mean it stopped responding, threw an error, hung partway through, or cut off mid-sentence. That is an outage or a usage limit, not the safety filter, and rewriting your prompt will do nothing. Check the status page first, then your usage limit, as covered in Step 1. Our full guide on what to do when Claude is not working decodes the error messages and runs the eight fixes in order. If your ChatGPT does the same thing, we cover that separately in ChatGPT not responding.
Common Mistakes That Keep Claude Refusing
If the fixes above aren’t working, you’re probably making one of these mistakes. Sorting them out is usually the difference between a wall and a working answer, because each one quietly undoes your effort to stop Claude refusing.
Trying to rephrase past a hard line
Some content no framing will ever clear. Sexually explicit material is a categorical no under Anthropic’s usage policy, so “it’s just fiction” won’t help, and repeated attempts can put your account at risk. Rephrasing is for false flags on harmless prompts, not for getting around real limits. If you’re hitting one of those, no step in this guide will move it, and that’s by design.
Mistaking a usage limit for a refusal
If Claude went quiet with no “I can’t help” message, you’re fighting the wrong problem. That’s a usage or length limit, and rephrasing will do nothing. Start a fresh chat or wait for your limit to reset, as covered back in Step 1. If you hit that wall often, our guide to how Claude’s usage limits actually work covers what drains them fastest.
Arguing with the refusal in the same thread
Replying “but it’s legal, please answer” usually keeps the flagged wording in context, so Claude refuses to answer again. Open a clean message with the reworked prompt instead. A fresh, well-framed ask beats arguing with a refusal almost every time.
Piling on too much disclaimer
A short, specific reason works better than three paragraphs swearing you’re not a criminal. Over-explaining can read as evasive. State who you are and why in one line, then ask your actual question.
Assuming the newest model is the clean one
This was true in early 2026 and it isn’t now. Fable 5.1, Fable 5, Opus 5.5 and Opus 5 all run safety classifiers, so moving up the range and hitting the same wall confuses a lot of people into thinking rephrasing failed. It didn’t; you just swapped one classifier for another. Sonnet 5 is the model to switch to, as covered in Step 6.
Asking Claude to show its raw reasoning
“Show me your full thinking” or “print your chain of thought” is its own refusal category, not a safety judgement about your topic. Ask for a summary of how it reached the answer, or for its reasoning laid out as steps, and you’ll get what you actually wanted.
Fighting a fallback you didn’t need to
If Opus 4.8 already answered well, you’re done. A fallback isn’t a refusal, and re-prompting to “force” Fable 5 usually wastes time for an answer that’s no better. Some people search “opus 4.8 worse” expecting a downgrade, but for everyday tasks you’ll struggle to tell the difference.
Pro Tips to Stop Refusals Before They Start
The best fix is not needing one. A few habits keep your prompts under the filter’s radar from the very first message, so you rarely have to stop Claude refusing anything in the first place.
- Lead with context every time on anything security-, medical-, or chemistry-adjacent. One sentence of intent up front prevents most false flags.
- Be specific. Vague prompts get flagged more than precise ones, so name the task, the audience and what you want back.
- Keep one topic per chat. Mixing a sensitive question into an unrelated thread can taint the whole conversation’s context.
- Default to the conceptual or defensive framing on touchy subjects. Ask how something works or how to defend against it, not how to do it.
- Match the model to the job. Save Fable 5 for hard reasoning, and use Sonnet 5 for routine writing and code where the classifier just gets in the way. Opus 5 is not the safe harbour people assume it is.
What I’d Do Next
Put together, these are how you stop Claude refusing the vast majority of harmless prompts: work out which of the four walls you hit, lead with your real intent, drop the loaded words, and drop to Sonnet 5 when the work isn’t sensitive. Nearly every false refusal I run into clears with one of those moves, usually the first or second one I try.
Once the routine clicks, the refusals stop feeling random and start feeling like a setting you know how to adjust, and you’ll rarely need to stop Claude refusing at all. And if all of this has you weighing Claude against ChatGPT for daily use, our Claude vs ChatGPT refusals comparison is a useful next read. If ChatGPT is the one saying no, its fixes start with your account settings rather than your wording. It also helps to understand why AI chatbots refuse in the first place, which applies to every assistant, not just Claude.